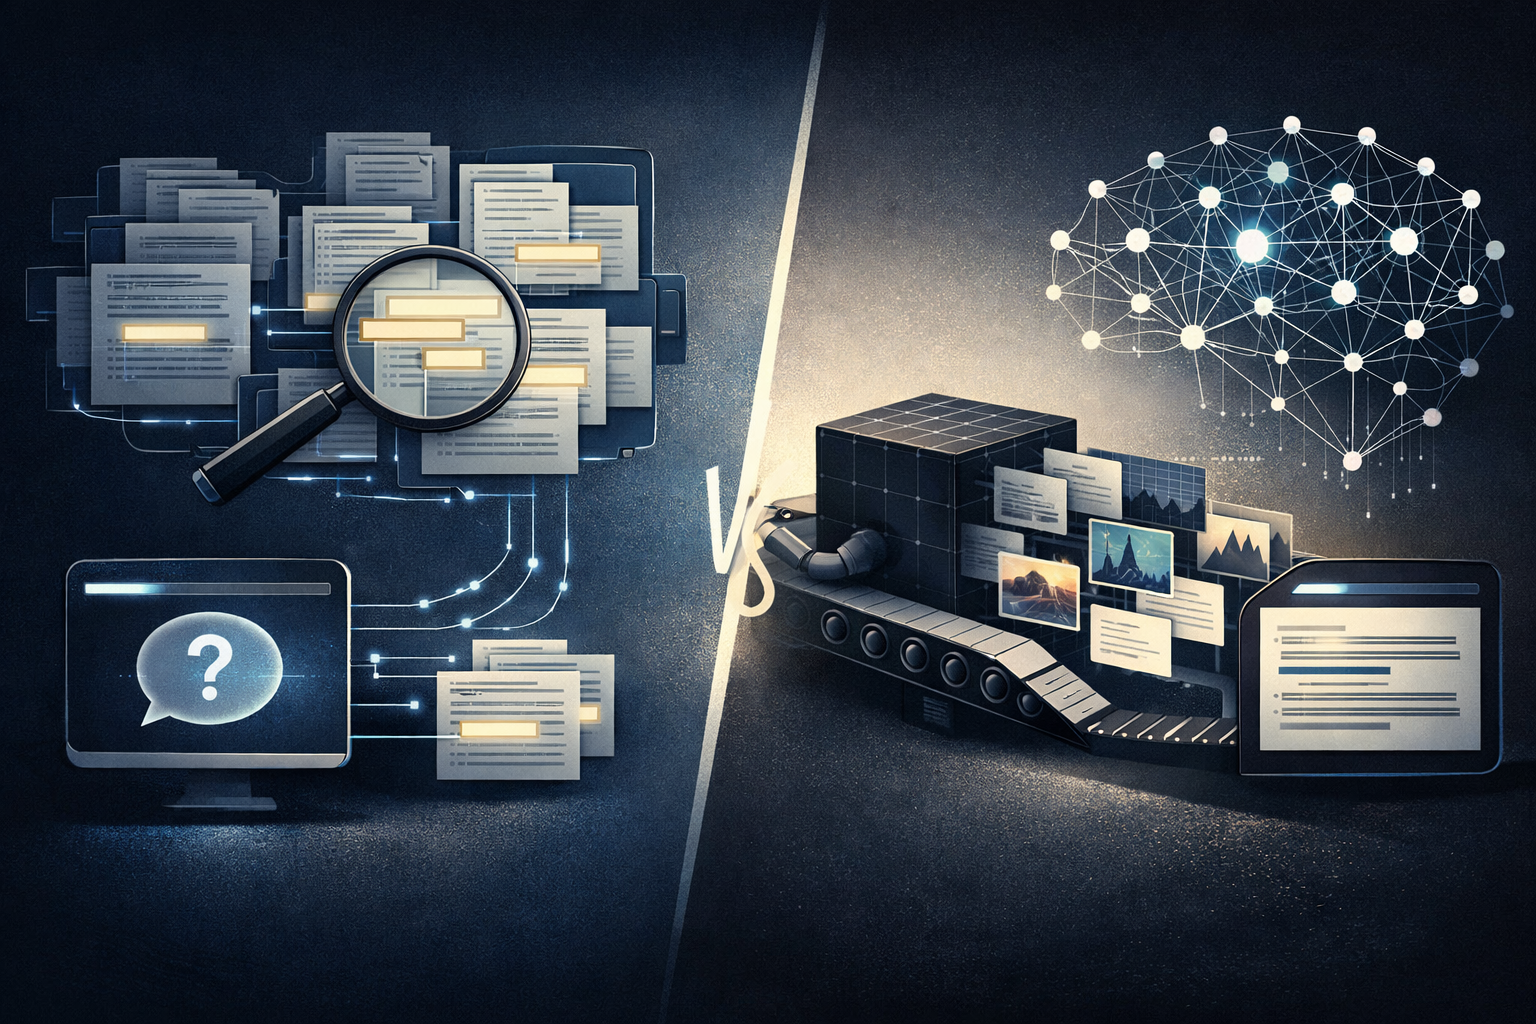
Fine-tuning vs. RAG is not a choice between two interchangeable ways to make a large language model smarter. It is a choice between two different customization patterns: one retrieves relevant information at query time, while the other trains a model to behave differently for a defined task.
For many production AI applications, the best answer is not either-or. RAG can provide the facts. Fine-tuning can improve how the model uses those facts, follows instructions, formats output, or handles a specialized workflow.
Fine-Tuning vs. RAG: The Short Answer
Use retrieval-augmented generation, or RAG, when your application needs to answer from external information: internal documentation, policies, product catalogs, support articles, legal or compliance material, or other knowledge that changes over time.
Use fine-tuning when your application needs more consistent behavior: a specific tone, output format, classification scheme, extraction pattern, workflow, or domain-specific response style that can be demonstrated through examples.
Use both when the system needs grounded knowledge and consistent task execution. A common hybrid pattern is to retrieve relevant context with RAG, then use a fine-tuned model to interpret that context in a predictable format or style.
The key distinction is simple:
- RAG is primarily about grounding answers in external data.
- Fine-tuning is primarily about changing model behavior for a task.
Microsoft describes RAG as a way to ground model outputs in data and notes that RAG and fine-tuning can be combined rather than treated as mutually exclusive approaches in its documentation on RAG and indexes in Microsoft Foundry. OpenAI similarly describes supervised fine-tuning as a way to customize model behavior from examples for a specific task in its supervised fine-tuning guide.
What Is Retrieval-Augmented Generation?
Retrieval-augmented generation is an architecture pattern in which an AI application retrieves relevant information from an external source and includes that information in the model prompt before generating an answer.
A typical RAG flow looks like this:
- A user asks a question.
- The system searches an index, document store, vector database, search engine, or other knowledge source.
- The most relevant chunks of content are added to the prompt as context.
- The language model generates a response using the retrieved context.
- The application may include citations, source references, confidence signals, or follow-up options depending on the design.
RAG is useful because the model does not have to rely only on what it learned during pretraining. It can use information retrieved at the time of the request. That makes RAG a strong fit for enterprise knowledge bases, customer support systems, policy assistants, product documentation bots, and applications that need to reference current or proprietary data.
The original RAG research paper introduced a model that combined parametric memory with retrieved non-parametric memory. However, the results in that paper apply to the specific architecture and experiments evaluated by the researchers. They should not be generalized as proof that every modern commercial RAG implementation will behave the same way. The paper is still useful background for understanding the concept; see the original Retrieval-Augmented Generation paper on arXiv.
What Is Fine-Tuning?
Fine-tuning is the process of training an existing model on examples so it performs better for a specific task or follows a desired pattern more reliably.
In supervised fine-tuning, the training data usually consists of input-output examples. These examples show the model what a good response should look like for a defined use case. Over time, the model adapts its behavior toward those examples.
Fine-tuning is often used when an application needs:
- A consistent response structure
- A specific writing style or tone
- Domain-specific wording
- Reliable classification behavior
- Structured data extraction patterns
- Repeated task handling that is difficult to achieve with prompting alone
- More consistent adherence to a workflow or decision pattern
Fine-tuning is not usually the best first choice for storing large volumes of changing factual knowledge. If the information changes frequently, a RAG system can often update the underlying knowledge source or index without retraining the model. Fine-tuning can include factual examples, but treating it as a substitute for an up-to-date knowledge retrieval layer can create maintenance and reliability problems.
Also, fine-tuning availability, supported models, pricing, and data handling rules vary by provider and can change over time. Teams should verify current vendor documentation before making architectural commitments.
Core Difference: Knowledge Grounding vs. Behavior Customization
The most common mistake in the fine tuning vs rag debate is assuming both approaches solve the same problem.
They do not.
RAG answers the question: What information should the model use right now?
Fine-tuning answers the question: How should the model behave when performing this task?
If your model gives polished but outdated answers, fine-tuning is probably not the first fix. You likely need better grounding through retrieval.
If your model has access to the right documents but still responds in the wrong format, uses the wrong tone, or inconsistently applies your task rules, fine-tuning may help.
In practice, many teams start with prompting and RAG because they need the model to access a trusted knowledge source. They consider fine-tuning later when evaluation shows repeated behavioral failures that better prompts and retrieval design do not solve.
When to Use RAG
RAG is a strong fit when the application must generate answers from external, proprietary, changing, or auditable information.
Use RAG for current or frequently changing information
If the answer depends on information that changes over time, RAG is usually a better architectural fit than fine-tuning. Examples include product availability, pricing rules, policy updates, release notes, support documentation, and internal procedures.
With RAG, the system can retrieve the latest available content from an index or knowledge source. That does not guarantee the answer will always be correct, but it avoids relying only on the model's training data.
Use RAG for proprietary or internal knowledge
Many business applications require the model to answer from company-specific material: sales enablement documents, HR policies, technical manuals, standard operating procedures, or customer support articles.
RAG can connect the model to that material at query time. This allows teams to keep knowledge in managed repositories rather than trying to encode everything into model weights.
Use RAG when citations or traceability matter
If users need to see where an answer came from, RAG is often the better starting point. A RAG system can be designed to show source documents, passages, or links that influenced the answer.
This is especially useful for enterprise search, compliance review, legal support, technical support, and other workflows where users need evidence rather than unsupported prose.
However, citations should still be evaluated carefully. A system can retrieve relevant documents and still generate an answer that overstates, misreads, or incompletely uses them. Retrieval quality, chunking, ranking, prompt design, and model behavior all affect reliability.
Use RAG for knowledge-heavy assistants
RAG is well suited for assistants that answer questions over large document collections. Examples include:
- Customer support knowledge base assistants
- Internal IT help desk bots
- Developer documentation assistants
- Policy and procedure assistants
- Product Q&A tools
- Research and knowledge management systems
In these cases, the main challenge is often not teaching the model a new style. It is giving the model access to the right information at the right time.
When to Use Fine-Tuning
Fine-tuning is a strong fit when you can define the desired behavior through high-quality examples and you need the model to perform a task more consistently.
Use fine-tuning for consistent output format
If the model repeatedly fails to produce the structure your application needs, fine-tuning may help. For example, you may need responses that follow a specific schema, classification label set, data extraction format, or workflow response template.
Prompting can often solve this at first. But if the format is complex, repetitive, or business-critical, fine-tuning may make the behavior more consistent for the target task.
Use fine-tuning for brand voice or response style
Fine-tuning can help align responses to a desired tone or writing style when that style can be demonstrated through examples. This may be useful for customer-facing assistants, sales enablement tools, or content operations workflows.
The important requirement is example quality. A fine-tuned model learns from the patterns it is shown. Inconsistent or low-quality examples can produce inconsistent results.
Use fine-tuning for domain-specific task behavior
Some tasks require more than access to facts. They require a consistent way of reasoning through a workflow, applying labels, extracting structured fields, or choosing among predefined response categories.
Fine-tuning can be useful for:
- Classification tasks
- Structured extraction
- Routing or triage decisions
- Rewriting content into a consistent format
- Applying domain-specific wording
- Following repeated task-specific instructions
This does not mean fine-tuning guarantees perfect accuracy. It means it can be a useful customization tool when the desired output pattern is well-defined and represented in training examples.
Use fine-tuning when prompting becomes repetitive or brittle
Some applications rely on long prompts that repeatedly explain the same behavior rules. Fine-tuning may reduce the need to restate those rules in every prompt in some cases.
That said, latency and cost outcomes are implementation-dependent. A fine-tuned model may reduce prompt length, but the total impact depends on the model, vendor pricing, traffic, infrastructure, and application design.
When to Use Both Together
RAG and fine-tuning can complement each other.
A hybrid architecture often looks like this:
- RAG retrieves relevant documents or data.
- The prompt provides that context to the model.
- A fine-tuned model applies a consistent task pattern, tone, format, or decision process to the retrieved information.
This can be useful when the application needs both factual grounding and predictable behavior.
For example, a support assistant may use RAG to retrieve relevant product documentation, then use fine-tuning to produce answers in a consistent troubleshooting format. A policy assistant may retrieve the latest HR policy and use a fine-tuned model to summarize it in a standardized employee-facing style. A document processing workflow may retrieve reference guidance and use fine-tuning to extract fields in a consistent schema.
The hybrid approach is especially useful when the model has access to the right information but still mishandles the task. RAG provides the content. Fine-tuning improves how the model uses it.
Decision Matrix: Fine-Tuning vs. RAG
| Decision factor | RAG is usually a better fit when… | Fine-tuning is usually a better fit when… |
|---|---|---|
| Data freshness | The answer depends on current or frequently updated information. | The task behavior is stable and does not depend primarily on changing facts. |
| Proprietary knowledge | The model must use internal documents, policies, or product data. | The model needs to follow company-specific behavior, tone, or formatting. |
| Factual grounding | You need answers grounded in retrieved sources. | You need the model to respond in a more reliable pattern for a defined task. |
| Output consistency | Retrieval supplies the needed facts, but formatting may still need prompt design. | The main issue is inconsistent structure, labels, tone, or workflow execution. |
| Maintenance | You want to update source content or indexes without retraining. | You can maintain a curated training set and update it when behavior requirements change. |
| Auditability | Users need source references or traceability to documents. | Users mainly need consistent task performance rather than source-backed answers. |
| Evaluation focus | Retrieval relevance, answer faithfulness, citation quality, and coverage matter most. | Task accuracy, format adherence, tone consistency, and example coverage matter most. |
| Latency | Retrieval adds steps, so performance depends on search, ranking, and generation design. | Fine-tuning may reduce prompt length in some cases, but latency depends on the model and deployment. |
| Security and privacy | Controls depend on the data sources, retrieval layer, vendor, deployment, and access rules. | Controls depend on the training process, vendor, deployment, and data handling policies. |
This matrix is a guide, not a universal rule. There is no reliable blanket claim that RAG or fine-tuning is always cheaper, faster, more accurate, or more secure. Those outcomes depend on implementation, model selection, data quality, traffic patterns, evaluation design, vendor pricing, and operational requirements.
Common Misconceptions
Misconception 1: Fine-tuning is the best way to add new knowledge
Fine-tuning can influence what a model learns from examples, but it is not usually the best way to manage large volumes of changing factual knowledge. If the application needs current or proprietary information, RAG is often the better starting point because it retrieves information from an external source at query time.
Misconception 2: RAG eliminates hallucinations
RAG can improve grounding, but it does not guarantee factual correctness. A RAG system can still fail if retrieval misses the right document, retrieves irrelevant context, chunks content poorly, ranks passages incorrectly, or prompts the model ineffectively. The model can also misinterpret retrieved information.
RAG reduces certain risks when designed well, but it is not a hallucination cure-all.
Misconception 3: Fine-tuning and RAG are mutually exclusive
They can be combined. Microsoft explicitly presents them as approaches that can work together, and many practical architectures use retrieval for knowledge grounding and fine-tuning for behavior customization.
Misconception 4: One approach is always cheaper or faster
Cost and latency depend on the details. RAG may add retrieval, ranking, and context assembly steps. Fine-tuning may reduce prompt length in some applications. But neither outcome is guaranteed. Pricing, infrastructure, model choice, caching, traffic volume, and vendor terms all matter.
Misconception 5: Fine-tuning automatically improves every task
Fine-tuning depends on the quality and relevance of training examples. If the task is poorly defined or the training data is inconsistent, fine-tuning may not solve the problem. Teams should evaluate whether prompt design, tool use, retrieval quality, or workflow changes would address the issue first.
Evaluation Checklist Before Choosing
Before committing to RAG, fine-tuning, or a hybrid approach, build an evaluation set that reflects real use.
Include:
- Representative user questions or tasks
- Expected answers or gold-standard outputs where possible
- Edge cases and ambiguous requests
- Examples involving outdated, missing, or conflicting information
- Security and access-control scenarios if the system uses private data
- Human review criteria for answer quality
For RAG systems, evaluate:
- Whether the retriever finds the right source content
- Whether chunking preserves enough context
- Whether ranking surfaces the best passages
- Whether the generated answer is faithful to retrieved context
- Whether citations or source references are accurate and useful
- Whether the system handles missing information appropriately
For fine-tuned systems, evaluate:
- Task accuracy
- Format adherence
- Tone and style consistency
- Performance on examples not seen during training
- Failure modes for edge cases
- Whether the model follows the desired workflow without excessive prompting
For hybrid systems, evaluate both layers together. A high-quality retriever does not guarantee a good final answer, and a well-tuned model cannot reliably answer from documents it never receives.
Worked Diagnosis: Fix the Failing Layer Before Training
Viva Paradox created this fictional support-desk exercise to make the choice testable. These are authored inputs and reference answers, not measured outputs from a model or a fine-tuning experiment.
The fictional product is DemoBox. Its retired document R1 says standard backups are retained for 30 days. The current document R2 explicitly replaces R1 and says standard backups are retained for 14 days. R2 also defines OUTAGE as “service unavailable” and DEGRADED as “service available but slow.” Treat these rules as exercise data, not a real product specification.
Using only the supplied current reference, answer: How long are standard backups retained? Return JSON with answer and source_id. If the reference is missing, say that the answer cannot be established. Do not substitute older documents.
Reference answer when R2 is supplied: answer states 14 days and source_id is R2. Valid JSON alone is insufficient: an answer stating 30 days still fails the factual check.
| Observed failure in the exercise | First change to test | Evidence required before escalating |
|---|---|---|
| The retrieved context contains only R1; the answer says 30 days. | Correct ingestion, version metadata, retirement filtering and retrieval. Retest whether R2 reaches the model. | Save retrieved document IDs and versions. Training a different writing style does not repair a stale index. |
| R2 is supplied; the answer correctly says 14 days but adds prose outside the required JSON. | Try a clearer prompt, supported schema-constrained output and application validation first. | Track parse/schema failures separately from factual errors. Fine-tuning is not required merely because one format attempt failed. |
| R2 is supplied; “available but slow” repeatedly receives OUTAGE instead of DEGRADED. | Check label definitions and examples. Compare a prompt baseline; consider fine-tuning only for persistent task errors with suitable labeled data. | Test on held-out cases. For an exact deterministic rule, ordinary application code may be simpler than a trained classifier. |
| A user receives a restricted team document that they are not allowed to read. | Enforce authorization in retrieval and application logic before generation. | Test with accounts with different permissions. Neither a refusal prompt nor fine-tuning replaces access control. |
A small comparison you can actually run
Create a separate held-out set containing current-document questions, missing-reference questions, OUTAGE/DEGRADED examples, and permission checks. Freeze the questions and reference answers before trying alternatives; do not copy held-out cases into training. For the three generation alternatives, hold the evaluation inputs, source versions, retrieval configuration and base model family fixed where feasible: (1) prompt plus current references, (2) the same system with improved instructions or supported output constraints, and (3) a fine-tuned variant only if justified. Record unavoidable differences. Test retrieval or permission repairs separately rather than attributing their effect to training.
Record, per case: whether the required source was retrieved, whether the answer is supported, whether the structure is valid, and whether the label is correct. Separately record permission-test failures, end-to-end latency and cost. Report counts with denominators and inspect disagreements; one combined score can hide a system that always emits valid JSON but uses obsolete facts. No accuracy, speed or cost gains are claimed by this exercise.
Choose the smallest change that fixes the observed failure on unseen cases. Keep retrieval when the application needs changing facts, and consider training for demonstrated behavior problems. A hybrid is a candidate to evaluate, not an automatic requirement.
Background: Microsoft distinguishes retrieval for private or changing data from fine-tuning for behavior, style and task performance. The diagnostic cases above are our own teaching examples.
For a reproducible retrieval and version-selection example, continue with our RAG practical guide.