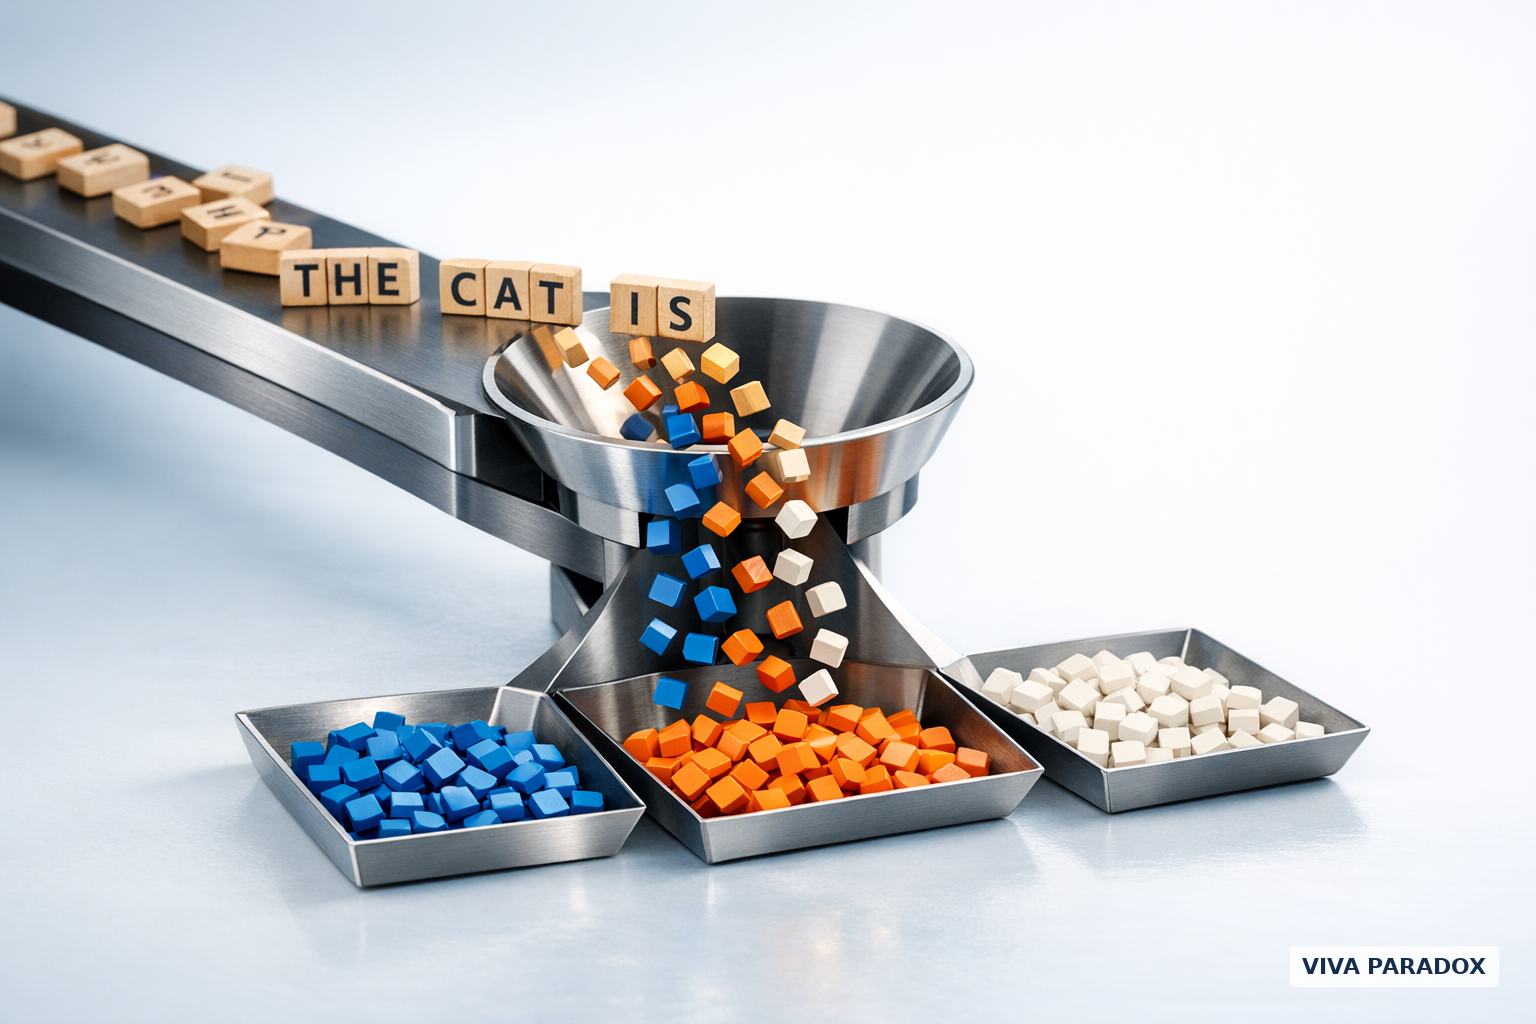
What are tokens in AI?
Tokens are the units of text that a large language model processes. A token might be a whole word, part of a word, punctuation, whitespace, or another text piece, depending on the tokenizer used by that model.
That means a token is not the same thing as a word. It is also not always a fixed number of characters. The important idea is simpler: before an AI language model can work with text, the text is converted into tokens. Google describes tokenization as part of how large language models convert text into a form they can process in its Machine Learning Crash Course introduction to LLMs. Microsoft similarly explains that token boundaries can vary and that language models operate over sequences of tokens in its LLM fundamentals guide.
This article is for people who use AI tools, write prompts, manage AI products, or build with LLM APIs and need a practical understanding of what tokens do. It does not cover every tokenizer implementation. Instead, it explains the working concepts that affect everyday use: prompt size, context limits, retrieved documents, code, chat history, and generated output.
Why LLMs use tokens instead of reading text like humans
Humans see words, sentences, formatting, tone, and meaning all at once. A language model needs a more structured representation. Tokenization is the preprocessing step that breaks input text into processable units before the model handles it.
For example, a model does not simply receive a page of English text as a human would read it. The text is first split into tokens according to that model's tokenizer. The model then works with those token units internally.
This matters because tokenization is model-dependent. Different tokenizers may split the same text differently. English prose, source code, emojis, tables, long identifiers, and non-English text may not break into tokens in the same way. Because of that, a universal rule such as one token always equals a certain number of characters is not reliable.
A rough estimate may be useful for early planning, but exact counts should be checked with the tokenizer or tooling for the specific model you plan to use.
Tokenization example: one sentence, possible token pieces
Here is an illustrative example. It is not the verified output of a specific commercial tokenizer.
Input sentence:
Please summarize tokenization clearly.
A tokenizer might split that sentence into pieces such as:
- Please
- summarize
- token
- ization
- clearly
- .
Another tokenizer could split it differently. For instance, it might keep tokenization as one unit, split clearly into a root and suffix, or treat spaces and punctuation differently.
The useful lesson is not the exact split. The useful lesson is that the model processes pieces, not human-visible words. A word like tokenization may be one token in one system and multiple tokens in another. Punctuation may also become its own token or attach to a neighboring piece, depending on the tokenizer.
Why this affects a prompt:
Suppose your prompt says:
Please summarize tokenization clearly. Use three bullet points.
The model does not reason over that prompt as nine human-counted words. It processes the tokenized version of the prompt, plus any previous chat history, pasted document text, examples, system instructions, retrieval results, and output requirements that are included in the model's context.
Limitation of the example:
This example is a teaching aid. It does not establish the actual token count for any named model. If a prompt is close to a context limit or pricing threshold, use the tokenizer or token-counting tool for the exact model.
How tokens relate to next-token prediction
At a high level, LLMs generate text by predicting likely next tokens from the context that came before. Microsoft's LLM fundamentals guide describes this general pattern: language models use preceding context to predict the next token in a sequence.
That does not mean the model is only doing a simple word-by-word lookup. Modern LLM behavior is more complex than a basic autocomplete box. But next-token prediction is a useful high-level explanation of why tokens matter:
- Your prompt and context are converted into tokens.
- The model uses those tokens as prior context.
- It predicts a likely next token.
- That new token becomes part of the context.
- The process repeats until the response is complete or a stopping condition is reached.
The response you see is the readable text reconstructed from those generated tokens.
Why tokens matter when writing prompts
Tokens affect practical AI use in four main ways.
1. Context windows
A model can only consider a limited amount of tokenized content at once. This is usually called the context window. The context may include your current prompt, earlier messages, system instructions, retrieved documents, examples, tool outputs, and the model's generated response.
If the combined content is too large, the system may reject the request, truncate content, omit older context, or behave as if some information was not available. Exact behavior depends on the model and application.
2. Prompt design
A prompt with clear instructions and relevant evidence usually beats a prompt that includes everything just in case. Token limits force prioritization.
For example, if you paste a long report and then add a vague instruction such as summarize this, the model may have less room for detailed output or may not be able to use all of the material. A better prompt often separates:
- the task,
- the most relevant source text,
- the desired output format,
- constraints such as audience, tone, or length.
3. API cost and usage planning
Some AI services price or meter usage by tokens. This article does not state current prices because vendor pricing changes and depends on the specific model. If cost matters, check the vendor's current documentation and count tokens using the model-specific tooling.
The practical point is stable: more input tokens and more output tokens generally mean more token usage. Long chat histories, pasted documents, and verbose generated answers can all increase usage.
4. User-facing behavior
Token pressure can show up as confusing behavior. A model may ignore a detail buried deep in a long prompt, produce a shorter-than-expected answer, lose track of earlier instructions, or struggle when the prompt contains dense code or tables.
Those outcomes are not always caused by token limits, but token load is one of the first things to inspect when a prompt works on a small example and fails on a larger one.
A practical decision rule for token-heavy prompts
Use this rule when a prompt, retrieved document, or conversation is near a model's context limit:
Keep the task instructions and the most relevant evidence. Summarize, compress, or remove lower-value material before adding more text.
In practice, that means:
- Keep the user's actual question.
- Keep constraints that change the answer, such as audience, jurisdiction, format, or source requirements.
- Keep the source passages most directly needed for the answer.
- Remove duplicate examples, repeated formatting, boilerplate, and irrelevant history.
- Summarize background material when exact wording is not necessary.
- Check exact token counts with the model's tokenizer when limits or costs matter.
The implication is important: adding more context is not always better. More text can crowd out the parts that matter most.
Worked procedure: estimate whether a prompt is token-risky
The following is a fictional worksheet-style example. It is designed to show a decision process, not to report a measured token count.
Fictional input
You want an AI model to draft a customer-facing FAQ from these materials:
- A 200-word instruction block explaining the tone and audience.
- Three long support articles pasted in full.
- A table of product plan names and feature descriptions.
- Five example FAQs from last quarter.
- A final instruction: Return concise answers in plain English.
Step 1: Separate the prompt into parts
Label the prompt content by purpose:
- Task: Draft a customer-facing FAQ.
- Audience and tone: Plain English for customers.
- Source evidence: Support articles and product table.
- Style examples: Five previous FAQs.
- Output requirements: Concise answers.
Step 2: Inspect what is likely to be token-heavy
The most token-risky parts are probably the full support articles and the feature table. Tables can contain repeated formatting, many short cells, punctuation, and product names. Long examples also consume context, especially if they are included in full.
This does not prove the token count. It identifies what to check.
Step 3: Apply the decision rule
Before adding more instructions, reduce lower-value material:
- Keep the core task and output requirements.
- Keep only the support article sections that answer the FAQ topics.
- Convert the table into the few feature facts needed for the FAQ.
- Keep one or two representative examples instead of five, unless all five demonstrate materially different patterns.
Step 4: Verify if the prompt is close to a limit
If the prompt might be near the model's context limit, use that model's tokenizer or token-counting tool. Do not rely on a universal characters-per-token shortcut. Google and Microsoft both describe tokenization as a model processing step, and Microsoft notes that token boundaries are not fixed across all text and tokenizers.
Reference decision
A reasonable reference decision is to shorten the source material before submitting the final prompt. The reason is not that long prompts are always bad. The reason is that this specific prompt includes multiple full documents, a table, and several examples, while the task likely depends on only selected facts and a small number of style cues.
Boundary case
If the task were legal, compliance, or technical review where exact wording matters, summarizing source material could remove important details. In that case, the safer approach may be to split the work into smaller steps, retrieve the exact relevant passages, or use tooling designed for long-context review. The right choice depends on the task and the model's actual limits.
Realistic failure case: short-looking text that uses many tokens
A prompt can look short in ordinary word count and still be token-heavy.
Consider this fictional input:
Analyze the following IDs and explain which ones fail validation:
customer_account_region_us-west-2_enterprise_2024_09_30_batch_final_v17
customer_account_region_us-west-2_enterprise_2024_09_30_batch_final_v18
customer_account_region_us-west-2_enterprise_2024_09_30_batch_final_v19
To a human, this looks like only a few lines. To a tokenizer, long identifiers, underscores, repeated segments, numbers, and punctuation may split into many pieces. Code can behave similarly. So can CSV data, Markdown tables, logs, URLs, multilingual text, and emoji-heavy text.
The lesson is practical: do not judge token load by how short the prompt looks on the screen. Inspect the kind of text. Dense technical formatting often deserves a token check.
Common misconceptions about tokens
Misconception 1: A token is always a word
A token may be a word, but it may also be part of a word, punctuation, whitespace, or another text unit. The exact split depends on the tokenizer and input.
Misconception 2: A token always equals a fixed number of characters
This is not reliable. Tokenization varies by model, language, script, and content type. A rule of thumb may be acceptable for rough planning if it is clearly labeled as an estimate, but it should not be used for exact limits or billing-sensitive calculations.
Misconception 3: All LLMs tokenize text the same way
They do not necessarily use the same tokenizer. Even when two systems feel similar to users, their tokenization details can differ.
Misconception 4: Only the visible prompt counts
In many AI applications, the model's context may include more than the text you typed: system instructions, chat history, retrieved documents, examples, tool results, and output space may all matter. The visible prompt is only part of the picture.
Misconception 5: More context always improves results
More context helps only when it is relevant and usable. Extra text can make the prompt harder to manage and may compete with the most important instructions or evidence.
Key takeaways
Tokens are the text units an AI language model processes. Tokenization converts text into those units before the model works with it. At a high level, LLMs generate responses by predicting likely next tokens from the preceding context.
For everyday AI use, the most important point is variability. A token is not always a word, and it is not always a fixed number of characters. Token counts can change depending on the model's tokenizer, the language, the formatting, and the kind of text you provide.
When limits or costs matter, use the tokenizer or token-counting tool for the specific model. When a prompt feels overloaded, keep the task instructions and the most relevant evidence, then summarize or remove lower-value material before adding more text.