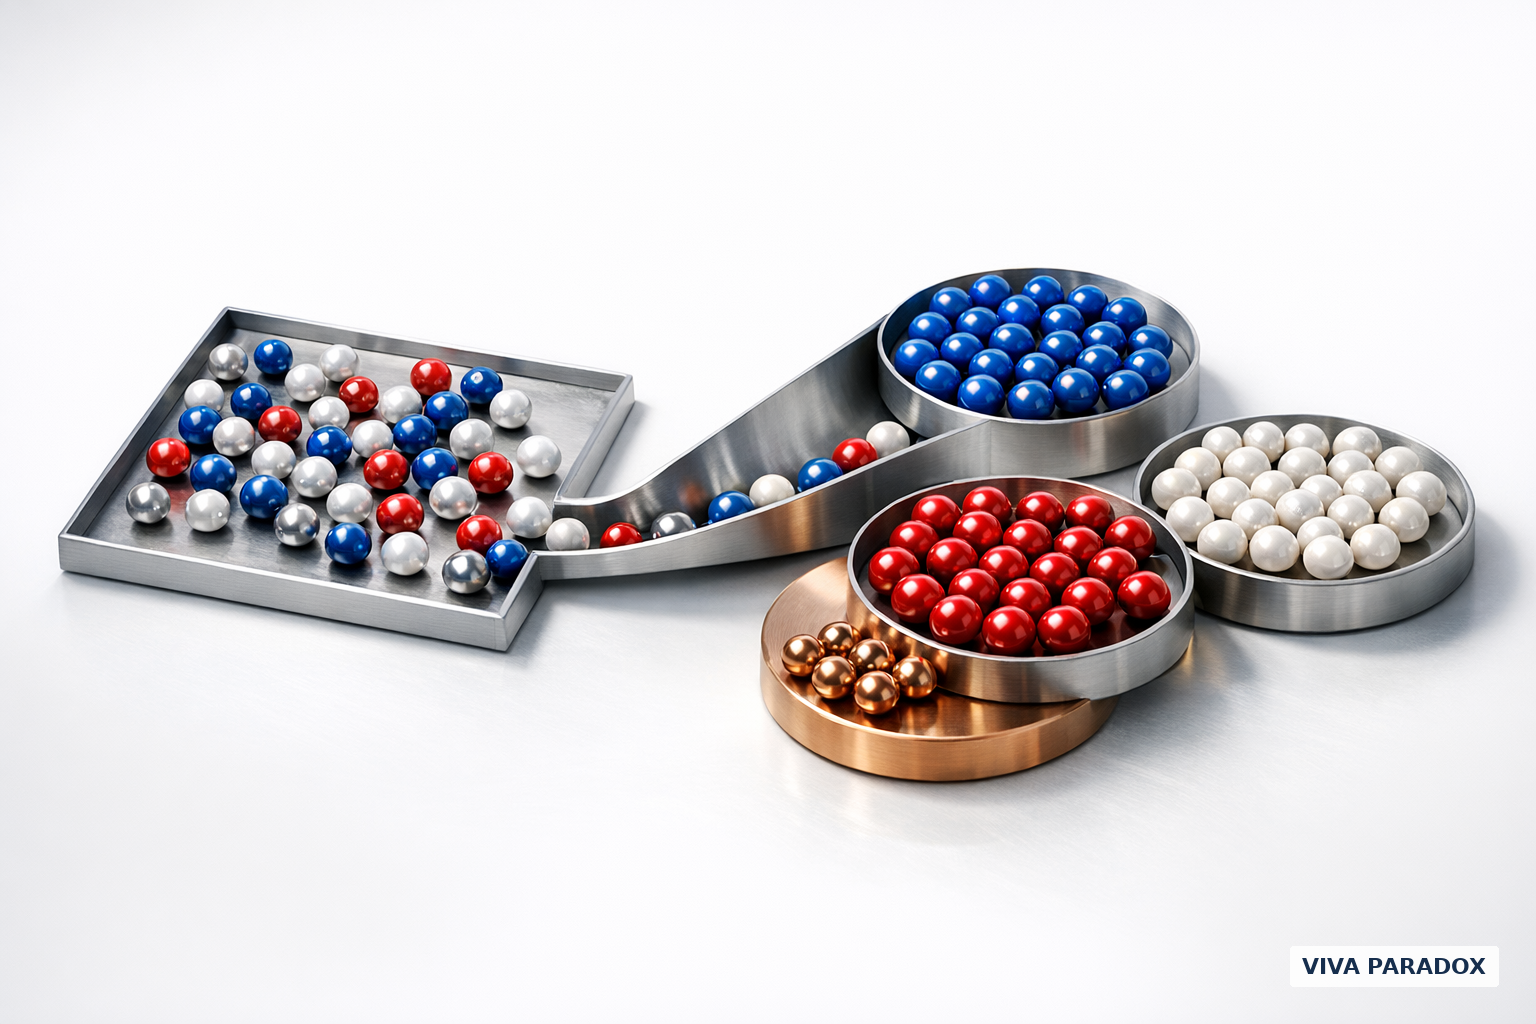
What clustering means in machine learning
Clustering in machine learning is an unsupervised learning task that groups unlabeled examples based on similarity. In other words, you do not start with a target label such as churned customer, fraudulent transaction, or premium product. Instead, the algorithm looks for records that appear similar according to the features you provide.
Google's Machine Learning Crash Course describes clustering as grouping unlabeled examples by similarity, which is the core idea behind the technique: the data has inputs, but not predefined answers (Google Machine Learning: clustering overview).
That definition is simple, but the practical meaning is more conditional: a cluster is only meaningful relative to the features, preprocessing choices, similarity concept, and algorithm used. If those choices are weak, the groups may be mathematically tidy but not useful.
What problem does clustering solve?
Clustering is useful when you have data and want to explore possible structure without already knowing the correct categories.
For example, a product analyst might have product records with fields such as:
- number of purchases
- average rating
- return rate
- discount frequency
- page views
If there is no existing label such as budget item, premium item, or risky item, clustering can help suggest groups worth inspecting. The result is not proof that those categories exist in the real world. It is a way to organize unlabeled data so people can review patterns more efficiently.
Use clustering when the question sounds like:
- Do these records naturally separate into similar groups?
- Are there segments that deserve different analysis?
- Which examples look similar under the features we selected?
Avoid clustering as the main technique when the question is already supervised, such as predicting a known outcome. If you have reliable labels and want to predict them for new examples, supervised learning is usually the more direct framing.
How clustering works at a high level
Most clustering workflows follow the same general pattern, even when the specific algorithm changes.
- Choose the examples to group. These could be customers, products, documents, sessions, transactions, or other records.
- Choose features that represent each example. The quality of the clusters depends heavily on these fields. Google notes that clustering usefulness depends on which features are chosen to represent the examples (Google Machine Learning: clustering overview).
- Preprocess the data. This can include handling missing values, encoding fields, and making feature scales comparable when needed.
- Choose a clustering method and similarity concept. The algorithm needs some way to decide which examples are close or similar.
- Form groups. The algorithm assigns examples to clusters according to its rules.
- Inspect the result. A person still needs to decide whether the clusters are useful for the business or analysis task.
The key implication is that clustering is not a neutral discovery machine. It is a model of similarity based on the representation you give it.
Illustrative worked example: clustering products by behavior
The following example is hypothetical and uses synthetic data. It is a reference walkthrough, not an executed experiment and not evidence of real model performance.
Input
Suppose an ecommerce team wants to explore whether products can be grouped by behavior. They do not have reliable labels for product type or quality. They choose three numeric features:
| Product | Monthly purchases | Average rating | Return rate |
|---|---|---|---|
| A | 900 | 4.8 | 0.02 |
| B | 850 | 4.7 | 0.03 |
| C | 120 | 4.6 | 0.01 |
| D | 100 | 4.5 | 0.02 |
| E | 700 | 2.1 | 0.25 |
| F | 680 | 2.3 | 0.22 |
Applicable rule
Clustering groups unlabeled examples by similarity. Here, similarity is based only on the selected features: monthly purchases, average rating, and return rate. That means any derived groups should be interpreted as groups under those features, not as objective product categories.
Steps
- Represent each product as a row with the three selected features.
- Preprocess the features so one field does not dominate only because of scale. Monthly purchases has much larger numeric values than return rate, so scaling choices matter.
- Choose a clustering method. K-means could be used as one possible method, but it is not the only clustering approach.
- Inspect the resulting groups and compare them with domain knowledge.
Reference answer, not an observed output
A reasonable analyst might expect three possible groups from this synthetic table:
- Products A and B: high purchases, high ratings, low returns
- Products C and D: low purchases, high ratings, low returns
- Products E and F: high purchases, low ratings, high returns
The reasoning is straightforward: A and B are similar across all three selected features, C and D are similar to each other, and E and F share the combination of strong purchase volume with weak satisfaction indicators.
Limitation
This example does not prove that there are three true product categories. If the team omitted an important feature, such as product price or category, the clusters might hide a more useful distinction. If the features were poorly scaled, the algorithm might group products mostly by monthly purchases and underweight rating or return rate. That would be a clustering failure caused by representation choices, not necessarily by the data itself.
K-means as one example of clustering
K-means is a common way to make clustering concrete, but it should not be treated as a synonym for clustering. Microsoft describes k-means clustering as a clustering method in Azure Machine Learning, which is the right level of specificity: it is one method within the broader clustering category (Microsoft Azure Machine Learning: k-means clustering).
At a high level, k-means is often introduced as a method that forms a chosen number of groups. That makes it useful for explanation because it forces the analyst to ask an important question: how many clusters should we look for?
The important editorial caveat is that choosing k-means also chooses a particular modeling assumption. If the data structure does not fit the assumptions behind the method, the resulting groups may be misleading. For a beginner, the safest way to think about k-means is: one practical example of clustering, not the definition of clustering itself.
Practical decision rule: when should you use clustering?
Use clustering when all three conditions are true:
- Your examples are unlabeled. You do not already have a trustworthy target category for each record.
- Your goal is exploratory grouping. You want to discover or summarize patterns, not predict a known answer.
- You can defend the features. The fields you use should plausibly represent the kind of similarity you care about.
Do not use clustering as a shortcut for a supervised prediction problem. If the goal is to predict whether a customer will cancel, whether a loan will default, or whether a transaction is fraudulent, and you have reliable historical labels, the problem is better framed as supervised learning.
A simple decision test is this: if success means matching known labels, clustering is probably not the right primary tool. If success means generating candidate groups for review, clustering may be appropriate.
Common failure case: clusters that look mathematical but are not useful
A realistic failure case is that the algorithm groups records according to irrelevant or poorly scaled features rather than meaningful categories.
Consider a customer dataset with these fields:
- annual spend
- number of support tickets
- account age in days
- preferred contact channel
If annual spend has much larger numeric values than the other fields and the workflow does not handle scale appropriately, the clusters may mostly separate high-spend from low-spend customers. That may be useful in some contexts, but it may miss the analyst's real question, such as whether customers need different support experiences.
The same problem can happen with irrelevant features. If preferred contact channel is included but has little to do with the intended segmentation, it may still influence the output depending on how the data is represented. The result can appear organized while answering the wrong question.
The implication: before interpreting clusters, ask what the algorithm was allowed to see. Clustering cannot recover meaning from features that do not represent the problem well.
How to interpret clustering results responsibly
Treat clusters as hypotheses, not ground truth.
A responsible interpretation should include:
- Feature review: Are the selected features relevant to the decision?
- Scale review: Could one feature dominate because of its numeric range?
- Domain review: Do the groups make sense to people who understand the data?
- Boundary review: Which examples sit near the edge between groups?
- Usefulness review: Does the grouping support a real decision, such as prioritizing analysis or designing a follow-up test?
This matters because clustering can always produce groupings under many configurations, but not every grouping deserves action. The value comes from connecting the mathematical grouping back to a clear analytical purpose.
Bottom line
What is clustering in machine learning? It is the process of grouping unlabeled examples by similarity. It is most useful for exploratory segmentation when you do not already have reliable labels. Its biggest limitation is also its central design choice: clusters depend on the features, preprocessing, similarity assumptions, and algorithm you choose.
Use clustering to generate candidate structure in unlabeled data. Do not treat the output as objective truth until the groups have been reviewed against the problem you actually need to solve.